Why Beans Is More Than a News API
Beans brings together public information, cleans up the labels and metadata, and ranks attention using observed engagement instead of publisher self-congratulation.
October 9, 2026Beans looks beyond the headline
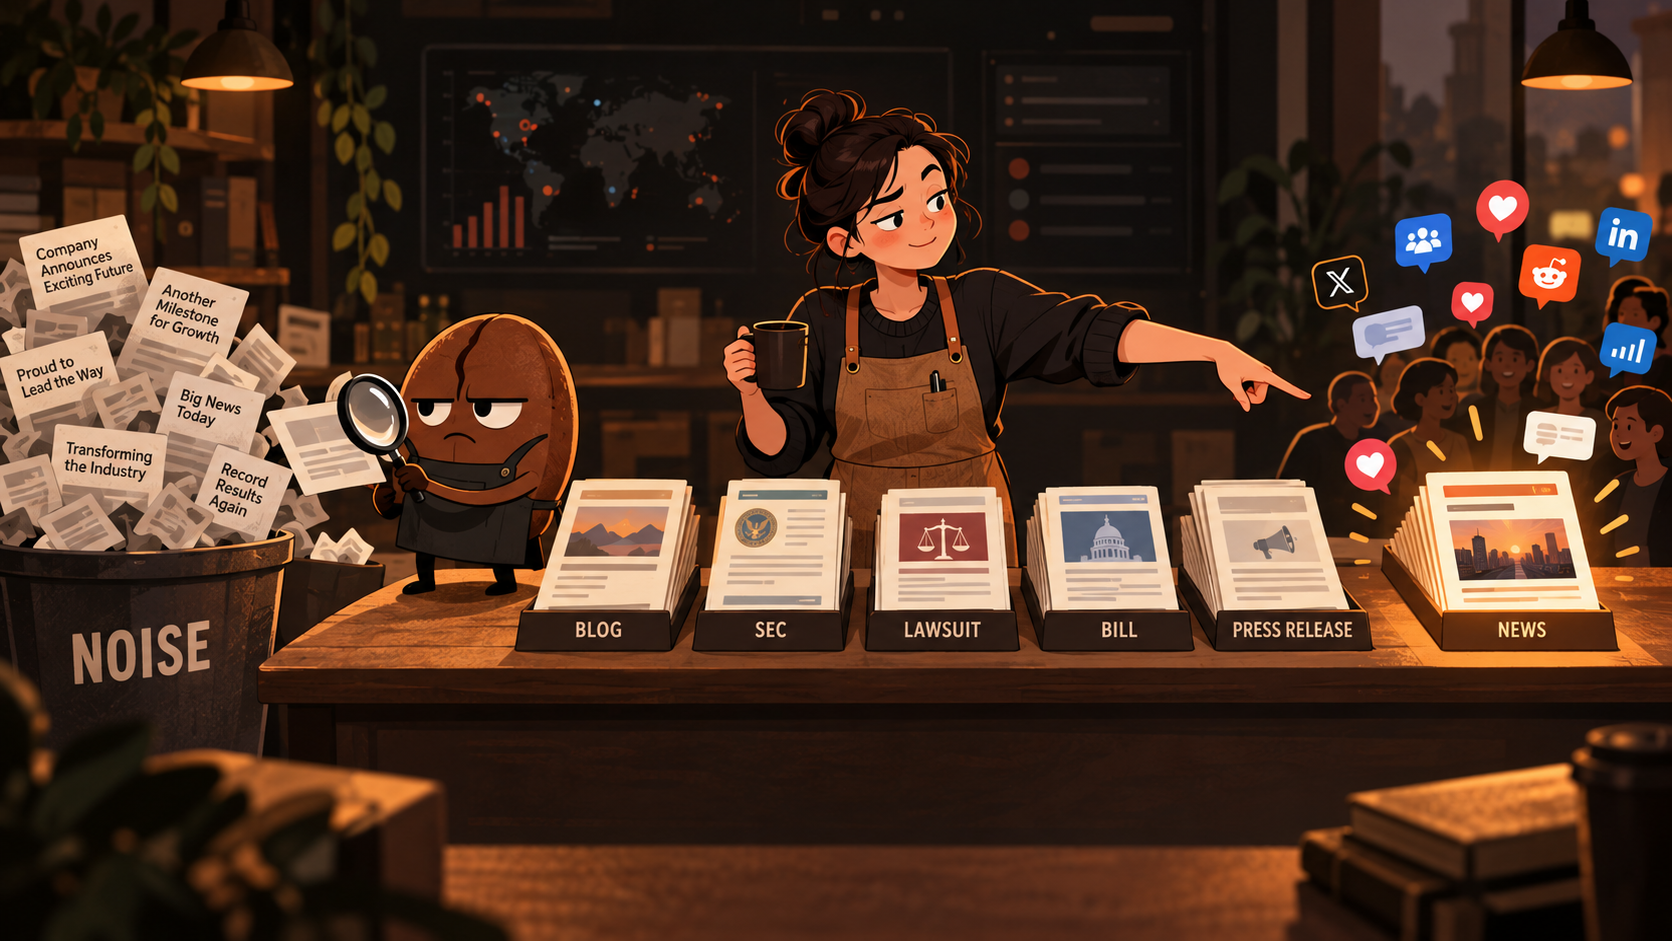
A headline can tell you what happened. It rarely tells you everything you need to decide what to do next.
A company announces a breakthrough. Fine. What did it file with the SEC? Is there a lawsuit? Did a bill proposal change the outlook? Is the conversation gaining traction beyond the publisher’s own website?
Beans brings those pieces into view. Alongside news, it covers blogs, press releases, financial reports, SEC filings, lawsuits, proposed legislation, research, and other public material. Because a decision built on one headline is still a decision built on one headline, however nice the headline looks in a dashboard.
A blog is a blog. This should not be controversial.
Different kinds of content deserve different treatment. A press release is useful, but it is a company speaking for itself. An opinion piece can be insightful, but it is not a reported news story. A puzzle with “today” in the title is probably not a developing world event.
We put real effort into telling these apart. We check what a piece is, where it came from, and what the page itself tells us. We clean up noisy titles, stray formatting, broken text, and other clutter that can make a feed harder to read or easier to misinterpret. When more information becomes available, we revisit the label.
That work is not glamorous. Nobody has ever asked to see a live demo of removing a publisher name from the end of a headline. But cleaner information makes it easier to compare sources, find the original material, and make a call with the right context.
Data quality is a decision-making feature
Good discovery is not just a large pile of links with a search box attached. It means separating reporting from commentary, recurring formats from actual developments, and primary documents from coverage about those documents.
Beans applies that editorial discipline across the collection. Titles are made more readable. Content is normalized. Obvious noise is filtered out. Source and page evidence help determine what an item actually is, instead of allowing a stray word like “news” to make the decision.
The result is a collection that is easier to filter and safer to use in a workflow. You can ask for news, blogs, lawsuits, earnings reports, or press releases and get a meaningful distinction rather than a taxonomy assembled by throwing a dart at a dropdown menu.
Trending should mean people are paying attention
“Trending” gets used rather generously on the internet. Sometimes it means a story has drawn a crowd. Sometimes it means somebody put it in a prominent box and hoped for the best.
Beans looks at observed attention, including social engagement and related coverage, when ranking what is trending. A publisher can call something its biggest story of the day; Beans looks for signs that the wider world agrees.
That distinction matters when you are deciding what needs attention now. You can follow the conversation without mistaking a publisher’s enthusiasm for public interest.
Beans is built for the moment after “I saw the headline.” You can look across reporting and source material, understand what kind of evidence you are reading, and see whether a story is gathering attention. It is a little more work on our end. That is rather the point.